DuckDB Tutorials, Benchmarks & Production Guides
DuckDB tutorials · Performance benchmarks · Production deployment guides
Code-first articles with runnable SQL and measured results
🔍 What is OLAP Studio?
OLAP Studio is a technical blog focused on DuckDB — the embedded columnar database designed for Online Analytical Processing (OLAP). We provide hands-on tutorials covering data analysis, ETL pipelines, and performance benchmarks. Every example is runnable, and every performance claim comes with its test conditions.
In published third-party benchmarks, DuckDB outperforms Pandas and SQLite across a range of analytical queries, and doesn't require complex cluster infrastructure like Snowflake. Whether you're processing multi-GB CSV files or building data pipelines, DuckDB makes you dramatically more productive.
📘
Tutorials
Learn DuckDB from scratch — data analysis, ETL, big data processing with real-world scenarios
⚡
Benchmarks
DuckDB vs Pandas/Polars/SQLite — data-driven comparisons to help you choose the right tool
🧩
Advanced Techniques
Window functions, JSON processing, macros and recursive CTEs — deep dives with runnable SQL
🛠️
Best Practices
Production deployment, performance tuning, common pitfalls — make DuckDB work for you
🧭 Learning Path
1
Basics
Install DuckDB and query CSV, Parquet and JSON files directly with SQL
2
Model
Joins, window functions, CTEs and aggregations on multi-GB datasets
3
Optimize
Read EXPLAIN plans, tune memory and threads, and benchmark against Pandas
4
Production
Ship scheduled pipelines, Parquet data lakes and embedded analytics
🔥 Featured Posts
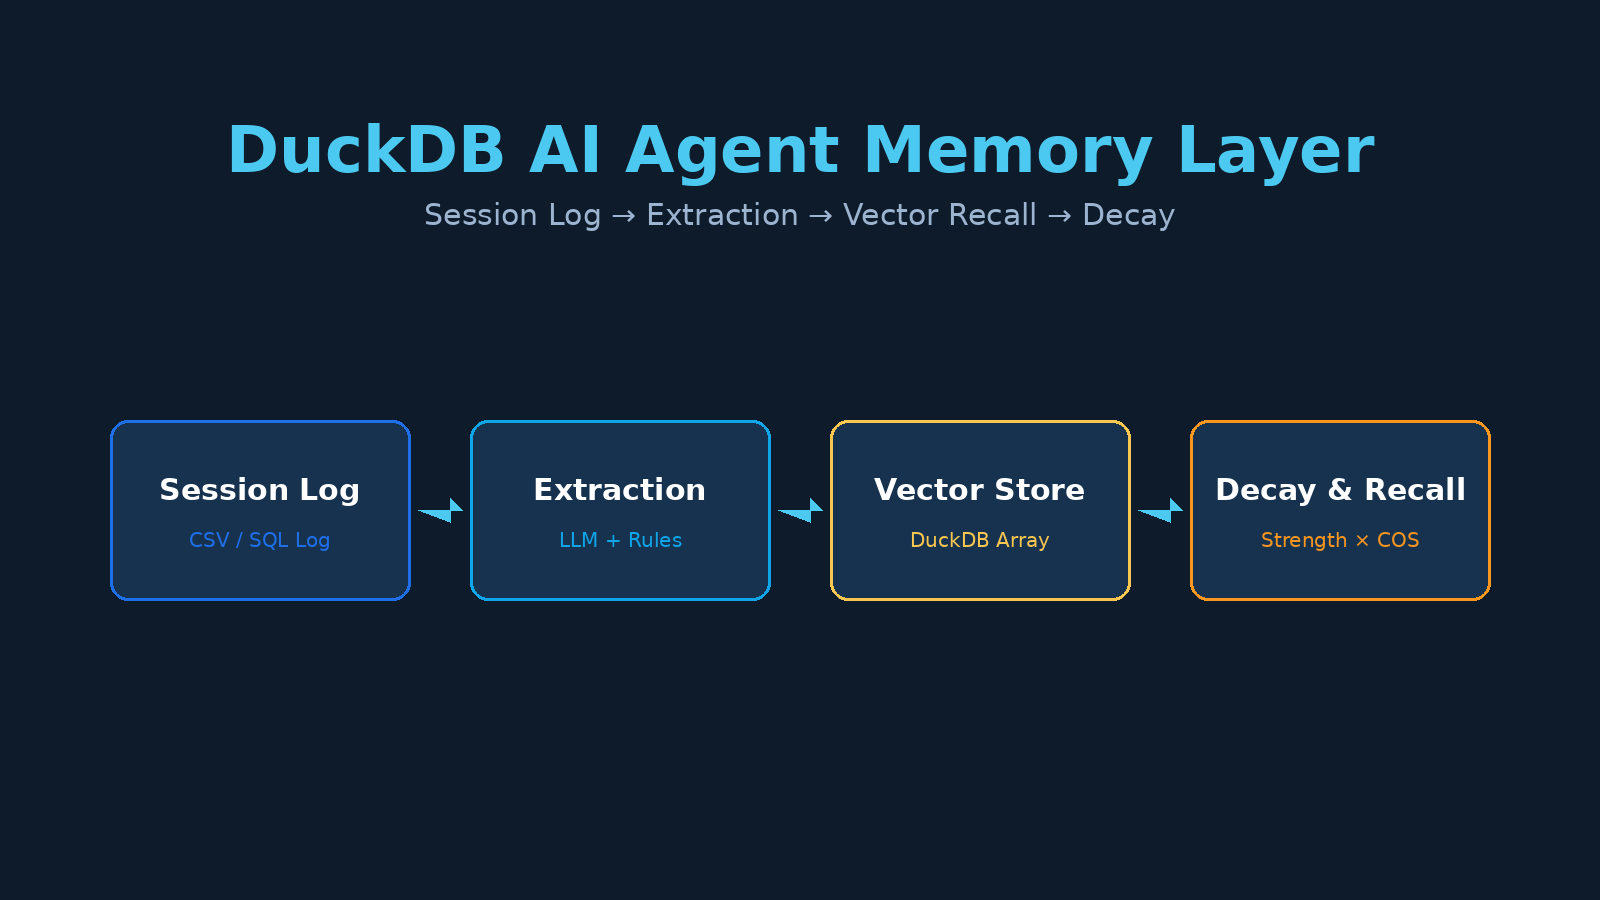
Building an AI Agent Memory Layer with DuckDB: From Session Logs to Long-Term Memory
Build an AI agent memory layer using DuckDB's built-in vector functions: session log extraction, vector recall, and memory decay/consolidation. Runnable code, DuckDB version noted, covering a core 2026 agent engineering problem.
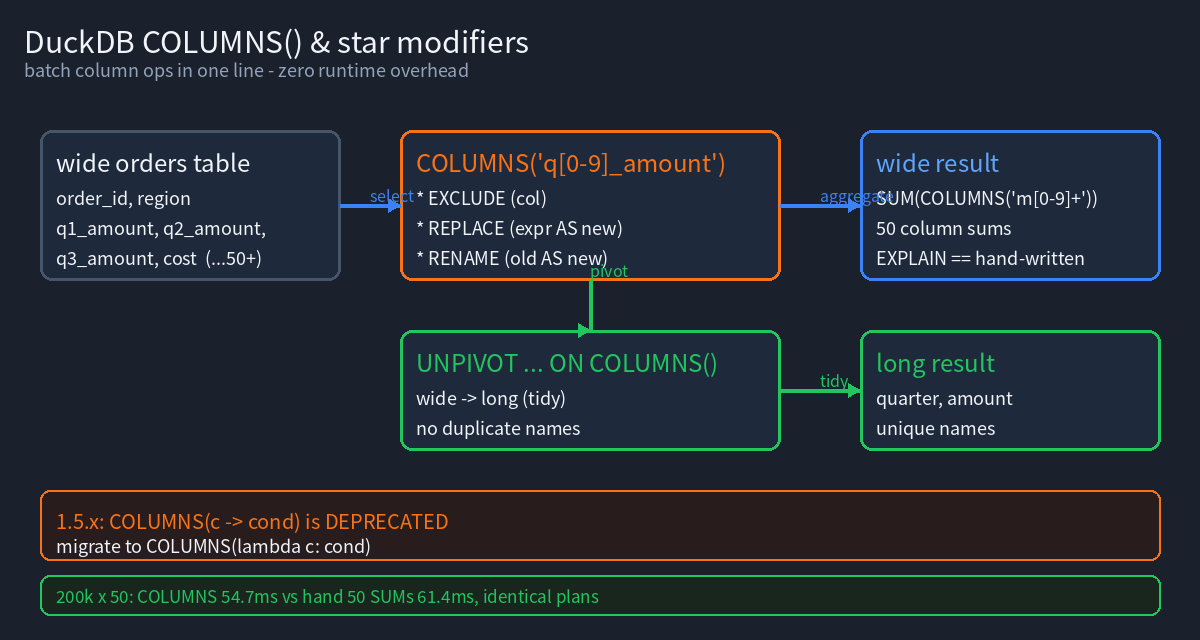
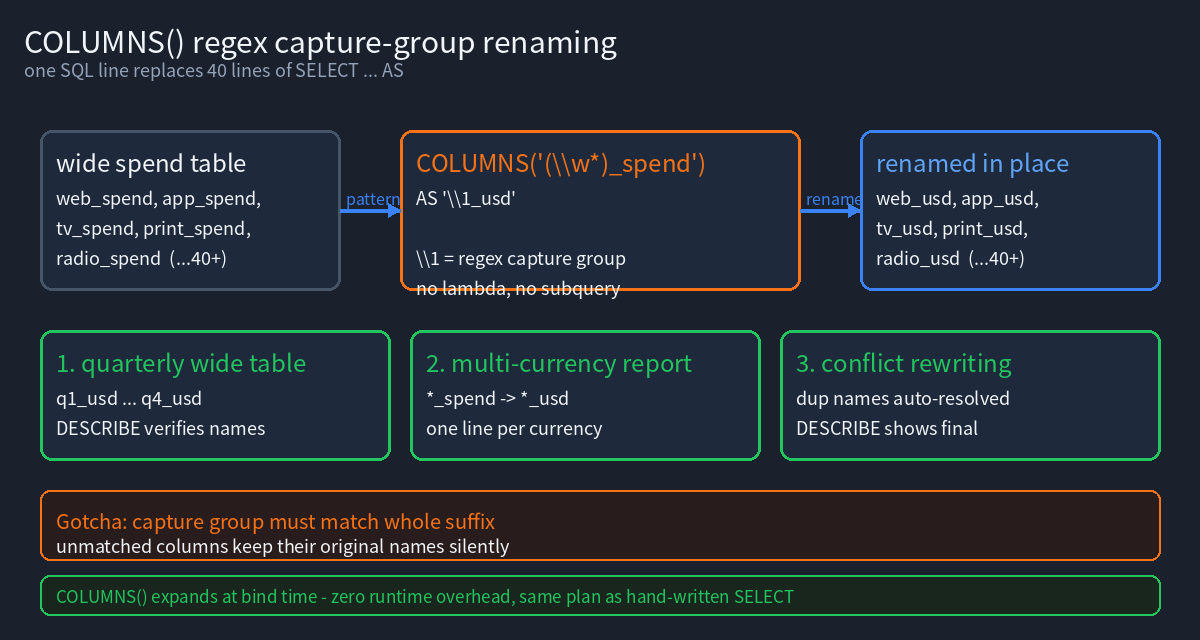
DuckDB COLUMNS() Expression & Star Modifiers: Batch Column Ops in One Line of SQL
DuckDB's COLUMNS() expression combined with star modifiers (EXCLUDE / REPLACE / RENAME) lets you batch-select, aggregate, and rename columns in a single line. Includes reproducible code and a plan-equality check on a 200k x 50-metric table.
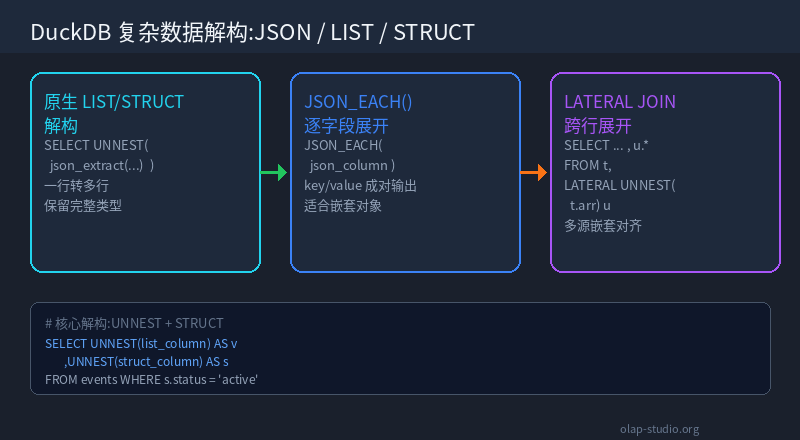
DuckDB Deep Dive: Unnesting Complex JSON and Array Data with STRUCT
Struggling with nested JSON or complex array data analysis? DuckDB's UNNEST function and STRUCT type are your powerful allies. This article demonstrates how to efficiently deconstruct and flatten these complex data structures through practical examples, making your data analysis simpler and more flexible. Say goodbye to tedious ETL steps and enjoy processing complex data directly in DuckDB.
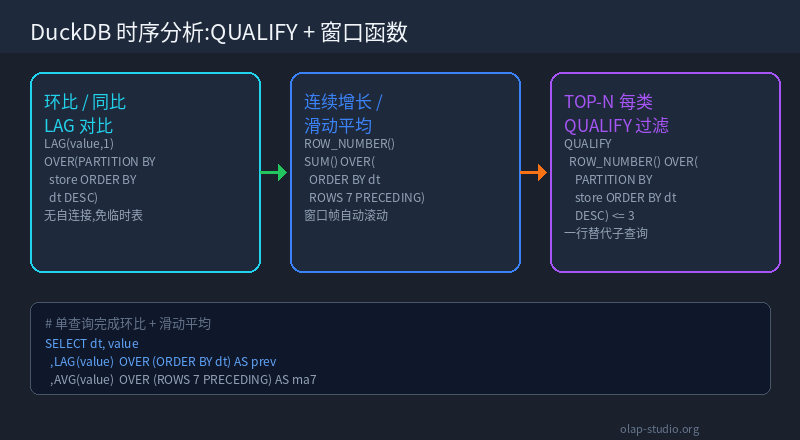
DuckDB Time Series Analysis: Power of QUALIFY and Window Functions
Struggling with complex time series data analysis? DuckDB's QUALIFY combined with powerful window functions allows you to effortlessly perform advanced analytics like day-over-day, year-over-year comparisons, and moving averages without subqueries or temporary tables, significantly boosting query performance and code clarity. This article delves into the powerful applications of this combination in real-time data analysis through practical examples.
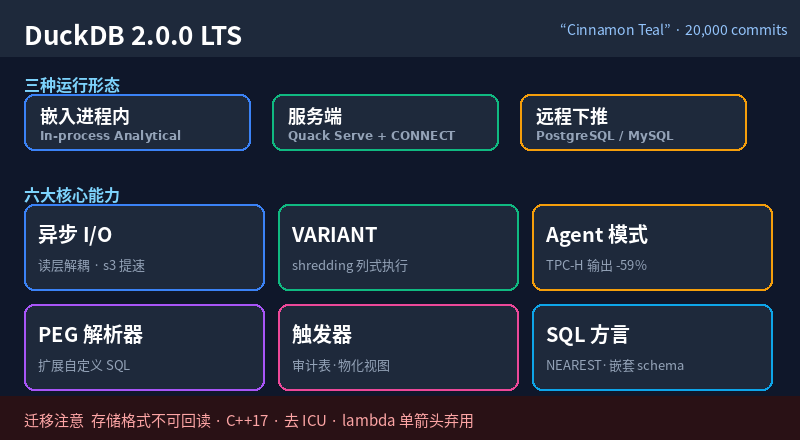
DuckDB 2.0 Deep Dive: From Embedded Engine to a Servable Database
DuckDB 2.0 LTS is not just another feature release. It promotes the Quack serving protocol, asynchronous I/O, a first-class VARIANT type, triggers, and the PEG parser into the core, reshaping what an embedded database can be. This post dissects each architectural change with runnable, 2.0-verified code plus a breaking-changes migration checklist.
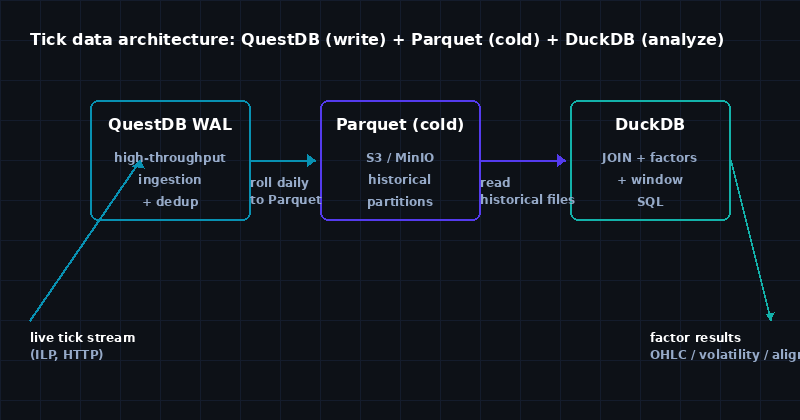
DuckDB for Tick Data Analysis: Why I Use QuestDB for Ingestion and DuckDB for Analytics
A practical tick data architecture: QuestDB handles high-throughput ingestion with WAL dedup, DuckDB handles factor computation and analysis with JOINs and window functions. Three reusable SQL patterns with test environment and results.
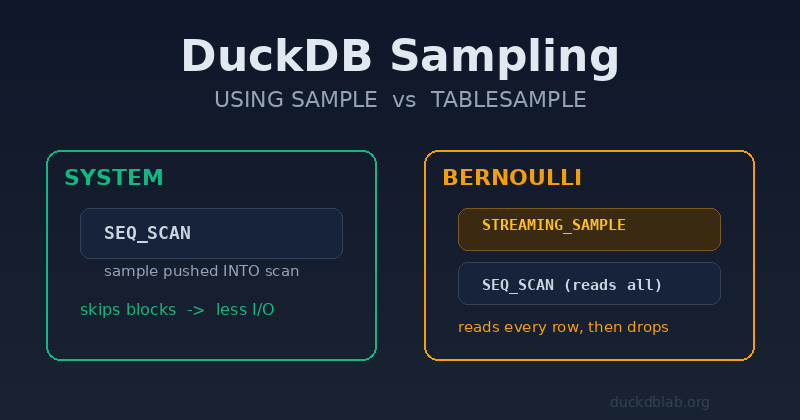
DuckDB Sampling in Depth: USING SAMPLE vs TABLESAMPLE (and When Sampling Is Slower)
A measured deep dive into DuckDB's USING SAMPLE and TABLESAMPLE: the SYSTEM, BERNOULLI and RESERVOIR methods, their hidden defaults, five syntax traps, and benchmarks showing when sampling actually beats a full scan.
📚 Keep Going Deeper
Work through these to get DuckDB into production (install → model → optimize → deploy)
❓ DuckDB FAQ
What is DuckDB best for?
Analytical querying — data exploration, ETL pipelines, large CSV/Parquet processing, embedded BI. It's not designed for OLTP workloads (high-concurrency transactions) — that's SQLite/PostgreSQL territory.
DuckDB vs Pandas: which is faster?
On GB-scale datasets, DuckDB is typically faster than Pandas on many analytical queries, while using less memory. Exact speedups vary significantly with data size, query shape, and hardware configuration. Our benchmark articles always state their test environment (see local benchmark).
Does DuckDB replace a data warehouse?
For single-machine analytics up to tens or hundreds of GB, often yes — DuckDB queries Parquet and Iceberg/Delta files directly with no cluster to manage. Beyond that scale, or for high-concurrency serving, a distributed warehouse is still the better fit.
How much data can DuckDB handle?
DuckDB handles 10GB-100GB datasets comfortably on a single machine. With Parquet format and partitioning, it can efficiently process TB-scale data. For most SMB analytics needs, DuckDB is more than sufficient.